uniq
Removes or counts repeated lines that follow each other.
Syntax
uniq [OPTION]... [INPUT [OUTPUT]]
Options
| Option | Description |
|---|---|
-c, --count |
Put the number of occurrences in front of each line |
-d, --repeated |
Only show lines that occur more than once |
-u, --unique |
Only show lines that occur exactly once |
-i, --ignore-case |
Ignore upper and lower case |
-f N, --skip-fields=N |
Ignore the first N fields when comparing |
Examples
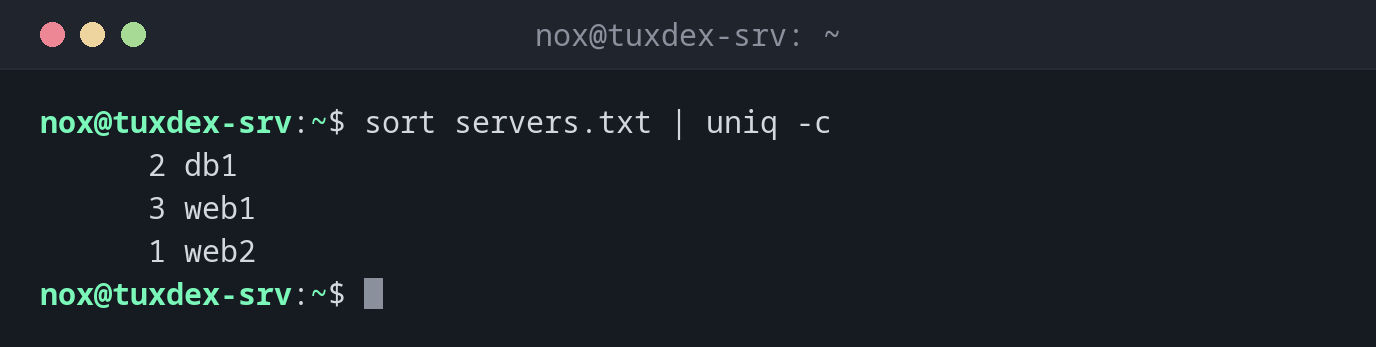
Count how often each line occurs:
sort servers.txt | uniq -c
      2 db1
      3 web1
      1 web2
Count the HTTP status codes in a log:
cut -d' ' -f9 /var/log/nginx/access.log | sort | uniq -c
      5 200
      1 302
      3 404
Find the IP addresses with the most requests:
cut -d' ' -f1 /var/log/nginx/access.log | sort | uniq -c | sort -rn
      4 198.51.100.23
      2 192.0.2.77
      2 192.0.2.10
      1 192.0.2.55
Only show lines that occur more than once:
sort servers.txt | uniq -d
db1
web1
uniq without sort:
uniq servers.txt
web1
db1
web2
web1
db1
web1
Nothing was removed, because the duplicates in the file are not next to each other.
When do I need it?
- To count how often something occurs in a log: IP addresses, status codes, URLs, error messages
- To find duplicates in lists, for example double entries in a user or host list
- To shorten a list to its unique entries
The classic pipeline
sort | uniq -c | sort -rn is one of the most useful command chains: it counts all
values and puts the most frequent ones on top. Add | head for a top 10.
Always sort first
uniq only compares a line with the one directly before it. Duplicates that are
spread over the file are only found after sort.