tr
Replaces, squeezes or deletes single characters in a text stream.
Syntax
tr [OPTION]... SET1 [SET2]
Options
| Option | Description |
|---|---|
| (none) | Replace each character from SET1 with the matching one from SET2 |
-d, --delete |
Delete all characters from SET1 |
-s, --squeeze-repeats |
Squeeze repeated characters into one |
-c, --complement |
Use all characters that are not in SET1 |
Useful character sets: a-z, A-Z, 0-9, [:upper:], [:lower:], [:digit:],
[:space:], '\n' (line break), '\r' (Windows line ending), '\t' (tab).
Examples
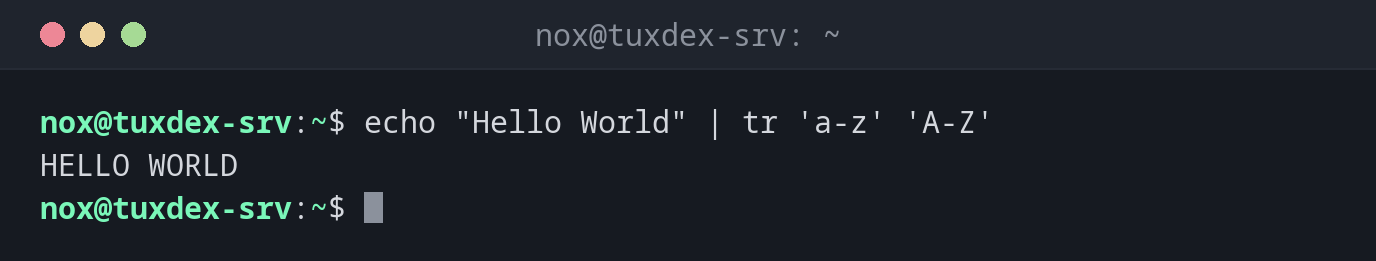
Convert to upper case:
echo "Hello World" | tr 'a-z' 'A-Z'
HELLO WORLD
Convert to lower case:
echo "Hello World" | tr '[:upper:]' '[:lower:]'
hello world
Remove Windows line endings from a script:
tr -d '\r' < deploy.sh > deploy-fixed.sh
file deploy-fixed.sh
deploy-fixed.sh: Bourne-Again shell script, ASCII text executable
Squeeze several spaces into one:
echo "too many spaces" | tr -s ' '
too many spaces
Show a colon-separated list line by line:
echo "/usr/local/bin:/usr/bin:/bin" | tr ':' '\n'
/usr/local/bin
/usr/bin
/bin
Generate a random password:
tr -dc 'A-Za-z0-9' < /dev/urandom | head -c 20; echo
q8ZkT3vNw1LpXa7RcY0m
-dc deletes every character that is not a letter or digit, so only those remain.
When do I need it?
- To fix files with Windows line endings (
tr -d '\r') - To normalise upper and lower case before comparing or counting
- To split lists like
$PATHinto lines, or to join lines into a list (tr '\n' ',') - To clean up output with multiple spaces before passing it to
cut
One entry per line
echo "$PATH" | tr ':' '\n' shows every directory in your search path on its own
line. That makes it much easier to read.
tr only reads from standard input
tr does not take a file name. tr a b users.csv fails with
tr: extra operand ‘users.csv’. Use tr a b < users.csv or a pipe instead.
No umlauts
GNU tr works byte by byte. Characters like ä or é consist of several bytes in
UTF-8 and are not converted, or are even broken. Use sed for such text.